

[Oct-2025] Verified Adobe Exam Dumps with AD0-E902 Exam Study Guide
Best Quality Adobe AD0-E902 Exam Questions PassCollection Realistic Practice Exams [2025]
NEW QUESTION # 26
A Fusion scenario is triggered by a project status update. The scenario then updates the status, causing repeated execution of the scenario.
Which action should a user take to keep this from happening?
- A. Schedule the instant trigger to only run at intervals to prevent Fusion from thinking the record has been updated after each run
- B. Create a filter after the instant trigger that only passes records that have not been updated by Fusion
- C. When using instant triggers, finish the scenario with the Break directive to prevent the record from being updated again
Answer: B
NEW QUESTION # 27
A Fusion scenario uses an HTTP module to create a new record.
Which response code indicates that the connection was successful?
- A. GREEN
- B. 0
- C. 1
- D. 2
Answer: C
Explanation:
* Understanding HTTP Response Codes:HTTP response codes are standardized codes that indicate the result of a request made to a server:
* 2xx (Success): Indicates that the request was successfully received, understood, and processed by the server.
* 200 OK: Specifically means that the request was successful, and the response contains the requested data or confirms the operation's success.
* Response Code for Creating a Record:
* When using an HTTP module in Fusion to create a new record, a response code of200confirms that the request to the server was successfully processed and the record creation was successful.
* Why Not Other Options?
* A. GREEN: This is not a valid HTTP response code. It might represent a status in some systems but is unrelated to HTTP standards.
* C. 402: This code indicates a payment required error, meaning the request cannot be fulfilled until payment is made.
* D. 500: This is a server-side error, indicating that something went wrong on the server during processing.
References:
* HTTP Status Code Documentation: 200 Success Response
* Adobe Workfront Fusion Documentation: HTTP Module and Response Codes
NEW QUESTION # 28
A Fusion scenario is triggered by a project status update. The scenario then updates the status, causing repeated execution of the scenario.
Which action should a user take to keep this from happening?
- A. Schedule the instant trigger to only run at intervals to prevent Fusion from thinking the record has been updated after each run
- B. Create a filter after the instant trigger that only passes records that have not been updated by Fusion
- C. When using instant triggers, finish the scenario with the Break directive to prevent the record from being updated again
Answer: B
Explanation:
Step by Step Comprehensive Detailed Explanation:
* Understanding the Problem:
* The scenario is triggered by a project status update.
* After the scenario runs, it updates the project status again, which re-triggers the scenario, creating aloop.
* The goal is to prevent the scenario from re-triggering itself.
* Option Analysis:
* A. When using instant triggers, finish the scenario with the Break directive to prevent the record from being updated again:
* Incorrect. The Break directive is not used to prevent updates; it is used to stop further iterations of a scenario. It does not address the root cause of the loop, which is the re- triggering by updated records.
* B. Create a filter after the instant trigger that only passes records that have not been updated by Fusion:
* Correct. Adding a filter ensures that only records not recently updated by Fusion are processed. This prevents Fusion from re-triggering itself on the same record.
* For example, you could use a condition to check if the Last Updated By field does not equal the Fusion user or if the Last Update Date is older than a certain threshold.
* C. Schedule the instant trigger to only run at intervals to prevent Fusion from thinking the record has been updated after each run:
* Incorrect. Instant triggers are event-driven, and their purpose is to respond to changes immediately. Scheduling them would negate the benefit of instant triggers and does not solve the root problem.
* Why Filtering Records is Best:
* Targeted Control: A filter after the trigger ensures only relevant updates (e.g., those not caused by Fusion) are processed.
* Prevents Loops: By excluding records updated by Fusion, the scenario avoids re-triggering itself.
* Maintains Performance: Filtering prevents unnecessary processing of irrelevant records, improving efficiency.
* How to Implement:
* After the instant trigger module, add a filter module.
* Configure the filter to check the Last Updated By field or a custom flag indicating if the update was performed by Fusion.
* Example: Last Updated By # Fusion User or Update Flag # True.
* If a custom flag is used, ensure the flag is set when Fusion updates the record.
* Alternative Solutions:
* Add a custom field (e.g., "Updated by Fusion") that Fusion sets when it updates a record. This can also be used in the filter condition.
References:This approach aligns with Fusion best practices for preventing infinite loops caused by scenarios re-triggering themselves. Filtering ensures the scenario runs only when necessary, avoiding redundant processing and maintaining performance.
NEW QUESTION # 29
A source system provides a list of users and their job roles and departments. The destination system requires the job role values be revised to match the job roles by different department. The end users currently use a spreadsheet to manage that mapping. Updates to this list are infrequent, and management requires more security than the current process offers.
Which method is appropriate for this use case?
- A. Table aggregator
- B. Data store
- C. Switch
- D. Spreadsheet
Answer: B
Explanation:
Step by Step Comprehensive Detailed Explanation:
* Scenario Summary:
* The source system provides a list of users, job roles, and departments.
* The destination system requires a mapping of job roles to different departments.
* Updates to this mapping are infrequent, and there is a concern for more security than a spreadsheet offers.
* Option Analysis:
* A. Switch: A switch function in Workfront Fusion is used to make decisions based on specific conditions but does not maintain persistent data like mappings over time. It is not suitable for storing mappings that require infrequent updates.
* B. Spreadsheet: Spreadsheets may be simple to use but are less secure and not ideal for integrating with Workfront Fusion workflows due to their lack of direct integration features or control over changes.
* C. Data store: Adata storein Workfront Fusion is specifically designed for storing persistent data, such as mappings or reference tables. It is secure, easy to manage, and integrates seamlessly with workflows, making it the best choice for this use case.
* D. Table aggregator: A table aggregator is used for combining or processing data within a workflow but is not suitable for storing persistent mappings outside of a running scenario.
* Why Data Store is Appropriate:
* Persistence: A data store is ideal for maintaining the job role and department mappings across scenarios.
* Security: It is managed within Workfront Fusion, offering better control and access restrictions compared to a spreadsheet.
* Ease of Integration: Data stores can be directly queried or updated in Fusion workflows, allowing seamless handling of mappings.
* Scalability: While updates are infrequent, the data store can handle changes easily and scale if the volume of mappings increases.
* Implementation in Workfront Fusion:
* Create adata storefor job roles and departments in Workfront Fusion.
* Set up fields for Job Role and Department in the data store.
* Use Workfront Fusion scenarios to retrieve and update mappings from this data store based on requirements.
References:This approach aligns with the Workfront Fusion documentation on data stores, which are designed for secure and efficient storage of persistent data used across scenarios. See Workfront Fusion resources for data store setup and use cases for further details.
NEW QUESTION # 30
Which statement about the differences between instant and polling triggers is true?
- A. To keep track of records processed, instant triggers store received webhooks in a queue, whereas polling triggers remember which records have already been processed
- B. A user should use instant triggers when available because instant triggers allow Fusion to process bundles of data faster than polling triggers
- C. A user must set up a webhook in Fusion to use Instant Triggers that make polling triggers easier to use and more reliable in scenarios
- D. Only polling triggers can be set to run on a schedule and should be used to avoid shutdown of third- party systems during working hours
Answer: B
Explanation:
* Understanding Instant and Polling Triggers:
* Instant Triggers:
* Rely on webhooks to receive real-time data from a third-party system.
* The external system sends a notification (webhook) to Fusion whenever an event occurs, triggering the scenario immediately.
* Polling Triggers:
* Regularly check (poll) the third-party system for new or updated records at scheduled intervals.
* These are slower because they involve repeated API requests.
* Why Option B is Correct:
* Speed and Efficiency:
* Instant triggers process data faster because they act immediately upon receiving a webhook. Polling triggers, on the other hand, may take time depending on the polling frequency and can result in unnecessary delays.
* Reduced Load on Systems:
* Instant triggers generate fewer API calls than polling triggers, which continuously check for new records even if no changes have occurred.
* Best Practice: Use instant triggers whenever supported by the third-party system to ensure faster and more efficient scenario execution.
* Why the Other Options are Incorrect:
* Option A ("Instant triggers store received webhooks in a queue"):
* Webhooks do not store data in a queue; they simply notify Fusion of events in real-time.
Polling triggers also do not store records but remember the last processed record.
* Option C ("A user must set up a webhook in Fusion"):
* Instant triggers require setting up webhooks in the external system, not in Fusion. Fusion provides the webhook endpoint, but the user must configure the source system to send data.
* Option D ("Only polling triggers can be set to run on a schedule"):
* This is incorrect because instant triggers do not rely on schedules; they operate in real-time.
Polling triggers, however, run on schedules and are used when instant triggers are unavailable.
References and Supporting Documentation:
* Adobe Workfront Fusion Triggers Documentation
* Workfront Community: Differences Between Instant and Polling Triggers Instant triggers are the preferred option when available, as they provide real-time data processing with greater speed and efficiency than polling triggers.
NEW QUESTION # 31
Data coming from a third-party system contains a field that needs to be transformed into one of three possible choices.
Which function supports this transformation?
- A. Switch
- B. Slice
- C. Split
Answer: A
Explanation:
* Understanding the Requirement:
* The field data from a third-party system needs to be transformed into one of three possible choices.
* This transformation implies conditional logic, where the output depends on the value of the input field.
* Why Option A ("Switch") is Correct:
* TheSwitchfunction evaluates a given input against multiple cases and outputs a corresponding value based on the matched condition.
* For example:
switch(field, "value1", "choice1", "value2", "choice2", "defaultChoice")
* If field equals "value1", the output is "choice1".
* If field equals "value2", the output is "choice2".
* If no conditions match, the output is "defaultChoice".
* This functionality perfectly fits the requirement to transform the input into one of three possible choices.
* Why the Other Options are Incorrect:
* Option B ("Slice"):
* The slice function is used for extracting a portion of a string or array but does not support conditional transformations.
* Option C ("Split"):
* The split function divides a string into an array based on a specified delimiter. It is not designed for conditional logic or value mapping.
* How This Solves the Problem:
* The Switch function allows flexible and dynamic transformations, ensuring the field data is mapped to the correct choice based on its value.
References and Supporting Documentation:
* Adobe Workfront Fusion Functions Documentation
* Workfront Community: Using the Switch Function for Conditional Logic
NEW QUESTION # 32
A Fusion Developer receives frequent notifications that a specific Scenario has been stopped. Upon investigation, the developer notes that there is nothing wrong with the data or process in the scenario, but that the error always occurs on a specific module that calls a third-party system. The error recorded is consistently a service unavailable error, particularly during times of high network traffic to the target system.
Which action should the Fusion Developer take to reduce the number of times the scenario is automatically stopped by Fusion?
- A. Update the Scenario settings to automatically retry failed executions.
- B. Add an error handler to the Module and select a Break directive.
- C. Add an additional route after the failing module with a repeater to retry errors.
- D. Update the Module settings to automatically ignore failed executions.
Answer: A
Explanation:
In this scenario, the error consistently arises due to the unavailability of a third-party service during high traffic times. This is a temporary issue and does not indicate a problem with the data or process. The recommended approach in such cases is to configure the scenario to retry failed executions:
* Update Scenario Settings:
* In Workfront Fusion, you can configure scenarios to automatically retry a failed execution.
* This option ensures that temporary issues, like service unavailability, are retried after a delay, reducing the chances of the scenario being stopped permanently.
* This is particularly useful when dealing with network traffic spikes or third-party API throttling.
* Why Not Other Options?
* B. Update the Module settings to automatically ignore failed executions: Ignoring failed executions would cause incomplete or incorrect data to flow through the scenario, leading to potential downstream issues.
* C. Add an error handler to the Module and select a Break directive: While error handlers are useful, the Break directive stops the scenario from processing further, which is not ideal for a temporary issue.
* D. Add an additional route after the failing module with a repeater: Adding a repeater increases complexity and is unnecessary when the retry option is already available in scenario settings.
References:
* Adobe Workfront Fusion Documentation: Scenario Settings and Error Handling
* Experience League Community: Handling API Rate Limits and Errors in Workfront Fusion
NEW QUESTION # 33
Given the array below, a user wants a comma-separated string of all stat names.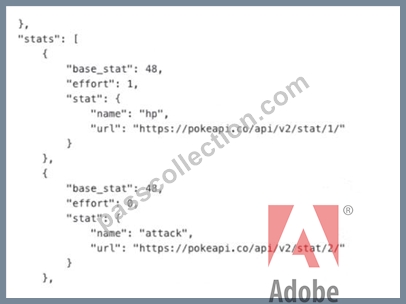
What is the correct expression?
- A.
- B.
- C.
- D.

Answer: C
Explanation:
* Understanding the Requirement:
* The input is an array containing objects, and the goal is to extract all the stat.name values into a comma-separated string.
* Example Input:
[
{
"base_stat": 48,
"effort": 1,
"stat": {
"name": "hp",
"url": "https://pokeapi.co/api/v2/stat/1/"
}
},
{
"base_stat": 48,
"effort": 0,
"stat": {
"name": "attack",
"url": "https://pokeapi.co/api/v2/stat/2/"
}
}
]
* Example Output:"hp, attack"
* Why Option B is Correct:
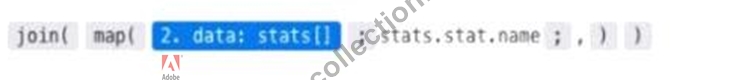
* The expressionjoin(map(2.data: stats[]; stats.stat.name); ", "):
* map: Iterates through each object in the array (2.data: stats[]) and extracts the stat.name field.
* join: Combines the extracted values into a single string, separated by a comma and space (", ").
* Breaking it down:
* map(2.data: stats[]; stats.stat.name) # Creates an array of names: ["hp", "attack"].
* join(...; ", ") # Converts the array into the string "hp, attack".
* Why the Other Options are Incorrect:
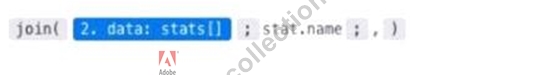
* Option A: join(2.data: stats[]; stat.name; ", ")
* This syntax is incorrect because it attempts to directly access stat.name within the join function without first mapping the values.
* Option C: join(map(2.data: stats[]; stat.name); ", ")
* The mapping references stat.name directly but does not account for the nested structure (stats.stat.name).
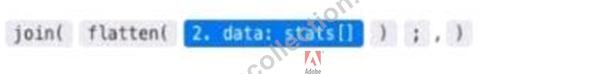
* Option D: join(flatten(2.data: stats[]); ", ")
* The flatten function is unnecessary here as the data is already structured. It would not properly extract the stat.name values.
* Steps to Implement in Workfront Fusion:
* Add aMapping/Transformation Module.
* Use the join(map(...)) function as described to transform the input array into a comma-separated string.
* Test the output to ensure it correctly generates the desired format.
* How This Solves the Problem:
* The map function ensures the proper extraction of nested stat.name values.
* The join function combines these values into the desired format efficiently.
References and Supporting Documentation:
* Adobe Workfront Fusion Functions Documentation
* Workfront Community: Using Map and Join Functions
The combination of map and join ensures that the stat names are extracted and formatted into a single comma-separated string, as required.
NEW QUESTION # 34
In this image,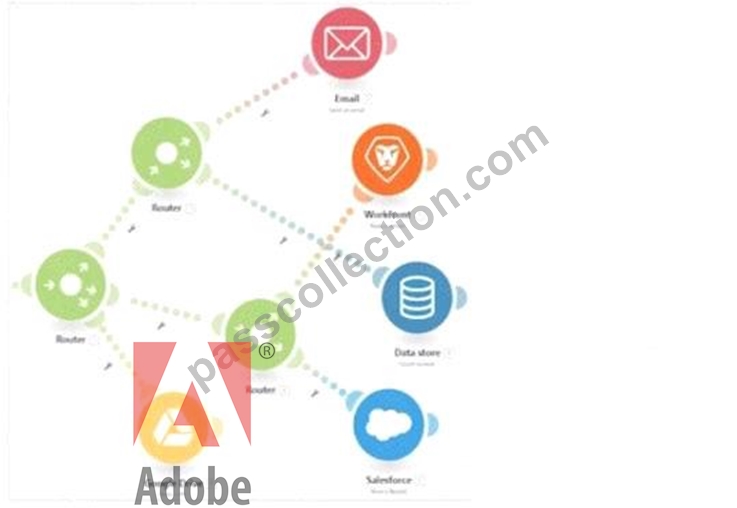
all items are displayed in a position that does not hide their execution sequence. In what order do the modules execute?
- A. Email > Data Store > Workfront > Salesforce >
- B. Email > Workfronl > Data Store > Salesforce > Google Drive
- C. Google Drive > Email > Workfront > Data Store > Salesforce
- D. Google Drive Google Drive > Email > Data Store > Workfront > Salesforce
Answer: D
Explanation:
* Understanding the Diagram:
* The image depicts a Workfront Fusion scenario usingRoutersto split and manage multiple execution paths.
* Fusion executes modules in aleft-to-rightandtop-to-bottomsequence along each path. Routers direct the flow to downstream modules.
* Determining the Execution Sequence:
* Path 1:
* The first path begins withGoogle Drive. The Router branches out, directing execution sequentially to other modules.
* Path 2:
* The second path starts withEmailand continues downwards through the remaining modules.
* Order Within Branches:
* After passing through a Router, each branch completes its sequence of modules before moving to the next Router.
* Why Option D is Correct:
* Execution begins from the leftmost module (Google Drive) and flows rightward. The sequence is as follows:
* Google Drive
* Email
* Data Store
* Workfront
* Salesforce
* This matches the visual layout and Fusion's execution rules for scenarios with Routers.
* Why the Other Options are Incorrect:
* Option A ("Google Drive > Email > Workfront > Data Store > Salesforce"):
* Incorrect becauseWorkfrontdoes not precedeData Storein the execution order.
* Option B ("Email > Workfront > Data Store > Salesforce > Google Drive"):
* Incorrect because execution begins withGoogle Drive, not Email.
* Option C ("Email > Data Store > Workfront > Salesforce"):
* Incorrect because it excludesGoogle Driveas the starting point and places modules out of sequence.
* Execution Rules in Workfront Fusion:
* Fusion executes modules in the order they appear visually, starting from left to right and top to bottom within each branch.
* Routers split the execution into separate branches, which are completed sequentially.
References and Supporting Documentation:
* Adobe Workfront Fusion: Execution Flow Rules
* Workfront Community: Understanding Router and Module Execution
The correct execution sequence is Google Drive > Email > Data Store > Workfront > Salesforce, ensuring all paths are processed as per the scenario's layout.
NEW QUESTION # 35
A custom API call to a web service is used inside of a high volume iteration. The module that calls the web service sometimes returns an error - 429: Too many requests.
Which two actions may be used to address this error? (Choose two.)
- A. Use an ignore directive on the module generating the error
- B. Use a break directive on the module generating the error
- C. Add a sleep module just prior to the module generating the error
- D. Add a module to test the service for errors
Answer: C,D
NEW QUESTION # 36
Which action in Fusion enables resource sharing, such as connections, data stores, and keys?
- A. Create a new group
- B. Create a new organization
- C. Create a new team
Answer: C
Explanation:
* Understanding the Requirement:
* The user wants to enableresource sharingin Fusion, includingconnections,data stores, andkeys.
* Resource sharing is necessary to allow multiple scenarios or users to access shared resources efficiently within the same Fusion environment.
* Why Option B ("Create a new team") is Correct:
* Teams in Fusion:
* Teams are a feature in Adobe Workfront Fusion designed to group users together within an organization.
* By creating ateam, you can enableshared accessto resources such as API connections, data stores, and authentication keys, streamlining collaboration and avoiding duplication.
* Resource Sharing with Teams:
* All members of the team can access shared resources (e.g., connections), allowing consistent and collaborative scenario development and execution.
* Example: If multiple users within a team need to use the same API connection, creating a team allows the connection to be configured once and shared among all team members.
* Why the Other Options are Incorrect:
* Option A ("Create a new group"):
* Groups in Fusion are used primarily for organizing scenarios or categorizing users but do not inherently allow sharing of resources like connections or keys. Groups lack the resource-sharing functionality of teams.
* Option C ("Create a new organization"):
* Organizations in Fusion represent the highest-level administrative entity. While creating an organization allows resource sharing among all users within the organization, it is not the recommended solution for managing resource sharing in smaller or more focused groups, such as project teams.
* Steps to Create a New Team and Share Resources:
* Log in to Adobe Workfront Fusion.
* Navigate to theAdmin PanelorTeam Managementsection.
* SelectCreate a New Teamand provide a name for the team.
* Assign users to the team by adding their Fusion accounts.
* Configure shared resources (e.g., connections, data stores, keys) to be accessible by the team.
* Save the settings, and all team members will now have access to the shared resources.
* How This Solves the Problem:
* Creating a team ensures that all resources, such as connections, data stores, and keys, are accessible to team members without requiring individual duplication or configuration. It simplifies collaboration and promotes consistency across scenarios.
References and Supporting Documentation:
* Adobe Workfront Fusion: Teams Overview
* Workfront Community: Managing Teams and Resource Sharing
NEW QUESTION # 37
A global customer has end users who input date and currency data into fields in inconsistent formats. Despite continued training efforts, this continues to be an issue. Unfortunately, the third-party service that the end users are using does not support forcing a required field format. These input mistakes do not happen frequently, but they currently stop the scenario from executing after the default three retries.
In Fusion, which action can the admin take to ensure that errors are corrected after they occur in a scenario?
- A. Use the switch module to catch dates not in the required format and convert the common misused patterns into the appropriate format to prevent the scenario from stopping after three failed executions.
- B. Set up an error handling path that will catch errors in the end user's inputs and message the users in an email update that they need to try again.
- C. Select storing of Incomplete Executions in the scenario settings. The customer admin can then filter and search the execution history to resolve errors as they occur.
Answer: C
Explanation:
* Understanding the Scenario:
* The issue involves end users inputting inconsistent date and currency formats that result in errors in a Workfront Fusion scenario.
* The default behavior of Fusion stops the scenario after three retries due to input mismatches or invalid formats.
* Why Option A is Correct:
* Storing Incomplete Executions: In Adobe Workfront Fusion, enabling "Store incomplete executions" in the scenario settings allows administrators to capture incomplete runs without fully stopping the entire process. This feature stores all relevant data, even from incomplete runs, allowing administrators to identify and correct input issues manually.
* Error Troubleshooting: By reviewing incomplete executions, admins can pinpoint where the scenario failed, resolve the issue, and potentially reprocess those incomplete records, preventing complete scenario stoppage.
* Why Option B is Incorrect:
* The "switch module" can handle specific input variations, but it is not a comprehensive solution for handling unexpected or inconsistent formats entered by end users. While it might mitigate some errors, it does not address the root cause and can miss unanticipated input patterns.
* Why Option C is Incorrect:
* Setting up an error handling path to notify users and request corrections adds an additional manual step for users but does not resolve the problem efficiently within Fusion. Moreover, this solution does not prevent the scenario from halting after retries.
* Steps to Enable Storing Incomplete Executions:
* Navigate to the scenario in Adobe Workfront Fusion.
* Open theScenario Settingsby clicking the gear icon.
* Enable the optionStore Incomplete Executionsunder Execution settings.
* Save the settings and activate the scenario.
* How This Solves the Problem:
* Enabling this setting ensures that no data is lost when the scenario fails due to inconsistent inputs.
Admins can access the incomplete executions through the scenario execution history, apply necessary corrections, and retry specific records or steps as needed.
References and Supporting Documentation:
* Adobe Workfront Fusion Official Documentation: Scenario Settings
* Workfront Community: Handling Incomplete Executions
NEW QUESTION # 38
A series of queries return several JSON packets that include a combination of nested arrays representing objects and their fields.
How should that information be arranged if each object needs to be processed through a portion of the scenario?
- A. Merge the JSON > Parse the JSON > then use the Iterator
- B. Concatenate the JSON > Define the data structures > Parse the JSON > then run the Iterator
- C. Define the data structure > Parse the JSON > then process arrays in the Iterator
- D. Define the data structure > then run the Iterator to Parse each JSON packet
Answer: C
Explanation:
Step by Step Comprehensive Detailed Explanation:
* Understanding the Problem:
* Multiple JSON packets with nested arrays are being returned by queries.
* The goal is to process each object within these JSON arrays through the scenario.
* Option Analysis:
* A. Define the data structure > then run the Iterator to Parse each JSON packet:
* Incorrect. While defining a data structure is necessary, running the Iterator first would fail to process the JSON properly if it is not parsed.
* B. Concatenate the JSON > Define the data structures > Parse the JSON > then run the Iterator:
* Incorrect. Concatenation is unnecessary for this scenario since each JSON packet can be parsed and processed independently.
* C. Define the data structure > Parse the JSON > then process arrays in the Iterator:
* Correct. The correct approach involves defining a data structure to map the JSON, parsing it to extract the data into usable fields, and then using an Iterator module to process each object in the nested arrays.
* D. Merge the JSON > Parse the JSON > then use the Iterator:
* Incorrect. Merging JSON packets is not required unless you explicitly need to combine data from multiple packets into a single structure, which is not mentioned in this scenario.
* Why This Workflow Works:
* Defining the Data Structure: Helps Fusion understand and map the JSON fields for processing.
* Parsing the JSON: Extracts the data into fields and arrays that can be further processed.
* Using the Iterator: Breaks down the nested arrays into individual objects for sequential processing through the scenario.
* Implementation Steps:
* Use aDefine Data Structuremodule to define the JSON schema (fields, arrays, and objects).
* Add aParse JSONmodule to convert raw JSON packets into mapped data fields.
* Add anIteratormodule to process individual objects in the nested arrays.
NEW QUESTION # 39
A Fusion scenario updates project conditions each night, and should set the project condition to At Risk if there are any high priority open issues on the project. The scenario retrieves all open projects and cycles through the projects. For each project with issues, it retrieves all associated open issues, iterates through them and sets the project condition to At Risk if the issue is high priority or On Target if it is not.
A user notices that Fusion is updating the progress condition multiple times, once for each issue in the project.
How can the developer ensure the project is updated only once?
- A. Record Add an Ignore error directive as an error handler route for the update module
- B. Change the issue search module to result set of First Matching
- C. Apply the Run Once flow control function
- D. Create a separate scenario to update the overall project condition
Answer: D
Explanation:
Step by Step Comprehensive Detailed Explanation:
* Problem Summary:
* The Fusion scenario updates the project condition multiple times, once for each high-priority issue.
* The desired behavior is to update the project condition only once, based on the overall condition of all associated issues.
* Option Analysis:
* A. Change the issue search module to result set of First Matching:
* This would limit the search to only the first issue. However, this does not account for all issues on the project, leading to incomplete logic for setting the project condition.
* B. Add an Ignore error directive as an error handler route for the update module:
* Ignoring errors does not prevent multiple updates; it only suppresses errors in the workflow.
* C. Create a separate scenario to update the overall project condition:
* Correct. By separating the project update logic into a different scenario, the developer can ensure the condition is updated only once after analyzing all issues. The project condition is calculated holistically, based on the state of all high-priority issues.
* D. Apply the Run Once flow control function:
* "Run Once" controls execution at the scenario level, not within a module's iteration. It cannot prevent multiple updates in this context.
* Why Separate Scenario is Best:
* Simplifies Logic: A separate scenario can be designed to run after all issues have been checked, ensuring only one update per project.
* Avoids Redundancy: Prevents unnecessary API calls to update the same project multiple times.
* Improves Performance: Reduces the number of operations and bundles processed in the main scenario.
* Implementation:
* Create a separate scenario triggered after the issue-checking scenario completes.
* Use aggregate data (e.g., a data store or intermediate processing) to evaluate the overall project condition before performing a single update.
NEW QUESTION # 40
A user needs to find a fields options within a custom form field. The details for the request are shown in the image below: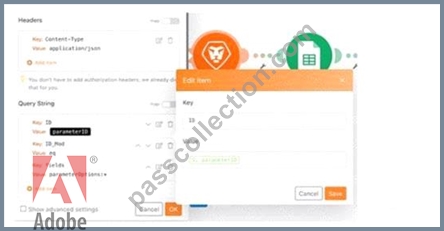
Which option is applicable for the URL text box?
- A. A screenshot of a web browser Description automatically generated
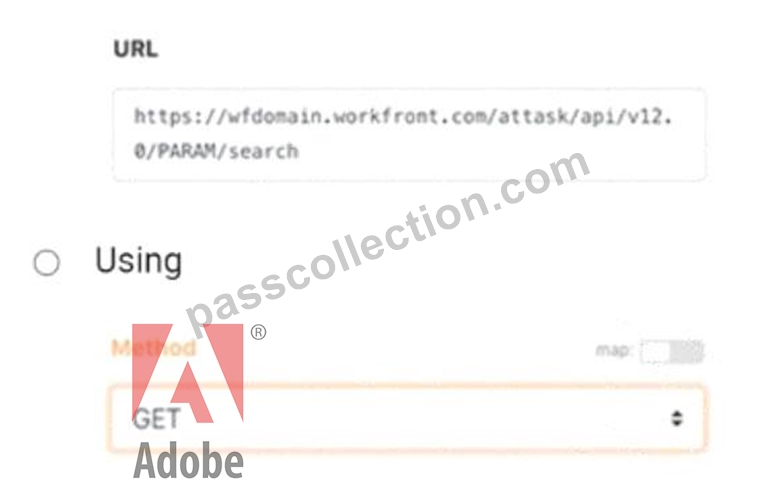
- B. A screenshot of a web page Description automatically generated
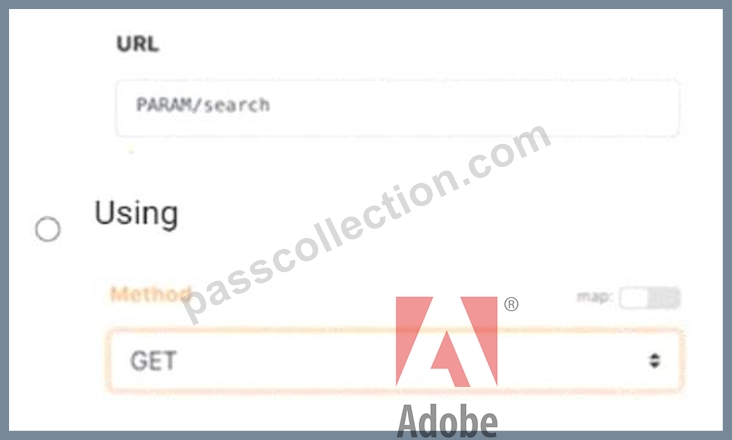
- C. A screenshot of a computer Description automatically generated

Answer: A
Explanation:
Step-by-Step Explanation
* Purpose of the Query:
* The task is to retrievefield optionsfrom acustom form field. This operation involves fetching data, not creating or modifying it, which requires a GET method.
* Correct API Structure:
* The URL must follow Workfront's API structure:
ruby
Copy
https://{your-workfront-domain}/attask/api/{version}/{endpoint}
* OptionBfollows this standard structure, where:
* wfdomain.workfront.com is the placeholder for the Workfront instance.
* /attask/api/v12.0 specifies the API version.
* /PARAM/search is the endpoint to search for parameters or fields.
* Why Not Other Options?
* A: The use of POST is incorrect because it is meant for creating or updating resources, not retrieving data. Additionally, the URL structure is incorrect and includes unnecessary query strings (username, password) not relevant for this operation.
* C: While the method GET is correct, the URL (PARAM/search) is incomplete and lacks the required Workfront API structure, making it invalid.
References
* Workfront API Documentation: Querying and Retrieving Custom Form Field Data
* Experience League Community: Best Practices for Using GET Methods in Workfront API=========================
NEW QUESTION # 41
......
Adobe AD0-E902 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
Authentic Best resources for AD0-E902: https://www.passcollection.com/AD0-E902_real-exams.html
AD0-E902 Test Engine Practice Exam: https://drive.google.com/open?id=1KCRZibAX38lXqUlfJI1zjTEnHKHIMPHs
