

Your social status should never limit your study options: whether you prepare at a desk or only during mealtime on a job site, the three Associate-Developer-Apache-Spark-3.5 versions at PassCollection put the material within reach.
Databricks Associate-Developer-Apache-Spark-3.5 Exam Overview:
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Associate Developer for Apache Spark 3.5 - Python |
| Exam Number: | Associate-Developer-Apache-Spark-3.5-Python |
| Exam Duration: | 90 minutes |
| Related Certifications: | Databricks Certified Data Engineer Professional Databricks Certified Data Engineer Associate |
| Passing Score: | 70% |
| Real Exam Qty: | 45-60 |
| Exam Format: | Multiple select, Multiple choice |
| Available Languages: | English |
| Exam Price: | $200 USD |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Apache Spark Documentation Databricks Academy - Apache Spark Training |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: |  |
| Exam Way: | Online proctored exam |
| Pre Condition: | Basic knowledge of Python programming and SQL is recommended. Familiarity with Apache Spark fundamentals is strongly suggested. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Objectives |
|---|---|
| Topic 1: DataFrame API with PySpark | - Transformations and actions - Built-in functions and expressions - DataFrame creation and schema management |
| Topic 2: Data Ingestion and Storage | - Reading and writing data (Parquet, JSON, CSV) - Delta Lake basics |
| Topic 3: Structured Streaming Basics | - Streaming DataFrames - Windowed aggregations in streaming |
| Topic 4: Spark SQL | - Window functions and aggregations - SQL queries on DataFrames and tables |
| Topic 5: Data Processing and Performance | - Caching and persistence strategies - Joins and data partitioning - Optimization techniques |
| Topic 6: Apache Spark Fundamentals | - RDD vs DataFrame vs Dataset concepts - Spark architecture and execution model |
Your Associate-Developer-Apache-Spark-3.5 Questions, Answered Around the Clock
- Spark SQL ()
- Structured Streaming Basics ()
- Data Ingestion and Storage ()
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
54 of 55.
What is the benefit of Adaptive Query Execution (AQE)?
- A. It optimizes query execution by parallelizing tasks and does not adjust strategies based on runtime metrics like data skew.
- B. It automatically distributes tasks across nodes in the clusters and does not perform runtime adjustments to the query plan.
- C. It allows Spark to optimize the query plan before execution but does not adapt during runtime.
- D. It enables the adjustment of the query plan during runtime, handling skewed data, optimizing join strategies, and improving overall query performance.
Correct Answer: D 🗳️
Explanation: Only visible for PassCollection members. You can sign-up / login (it's free).
3 of 55. A data engineer observes that the upstream streaming source feeds the event table frequently and sends duplicate records. Upon analyzing the current production table, the data engineer found that the time difference in the event_timestamp column of the duplicate records is, at most, 30 minutes.
To remove the duplicates, the engineer adds the code:
df = df.withWatermark("event_timestamp", "30 minutes")
What is the result?
- A. It removes all duplicates regardless of when they arrive.
- B. It is not able to handle deduplication in this scenario.
- C. It accepts watermarks in seconds and the code results in an error.
- D. It removes duplicates that arrive within the 30-minute window specified by the watermark.
Correct Answer: D 🗳️
Explanation: Only visible for PassCollection members. You can sign-up / login (it's free).
Given a DataFrame df that has 10 partitions, after running the code:
result = df.coalesce(20)
How many partitions will the result DataFrame have?
- A. 1
- B. Same number as the cluster executors
- C. 10
- D. 20
Correct Answer: C 🗳️
Explanation: Only visible for PassCollection members. You can sign-up / login (it's free).
Given the code fragment: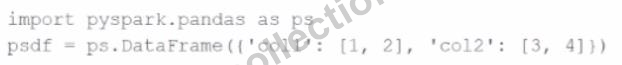
import pyspark.pandas as ps
psdf = ps.DataFrame({'col1': [1, 2], 'col2': [3, 4]})
Which method is used to convert a Pandas API on Spark DataFrame (pyspark.pandas.DataFrame) into a standard PySpark DataFrame (pyspark.sql.DataFrame)?
- A. psdf.to_spark()
- B. psdf.to_pyspark()
- C. psdf.to_dataframe()
- D. psdf.to_pandas()
Correct Answer: A 🗳️
Explanation: Only visible for PassCollection members. You can sign-up / login (it's free).
39 of 55.
A Spark developer is developing a Spark application to monitor task performance across a cluster.
One requirement is to track the maximum processing time for tasks on each worker node and consolidate this information on the driver for further analysis.
Which technique should the developer use?
- A. Use an accumulator to record the maximum time on the driver.
- B. Broadcast a variable to share the maximum time among workers.
- C. Configure the Spark UI to automatically collect maximum times.
- D. Use an RDD action like reduce() to compute the maximum time.
Correct Answer: D 🗳️
Explanation: Only visible for PassCollection members. You can sign-up / login (it's free).
Viewing page 1 out of 27 pages.
Viewing questions 1-5 out of 135 questions.


 Lance

 Hardy

 Kyle
 Jo
 Maggie

 Cornelia
 Murphy
 Ernest
 Clark
 Roy
 Greg
 Leona
 Debby
 Martina
 Tess


